How to Handle Missing Data in Machine Learning
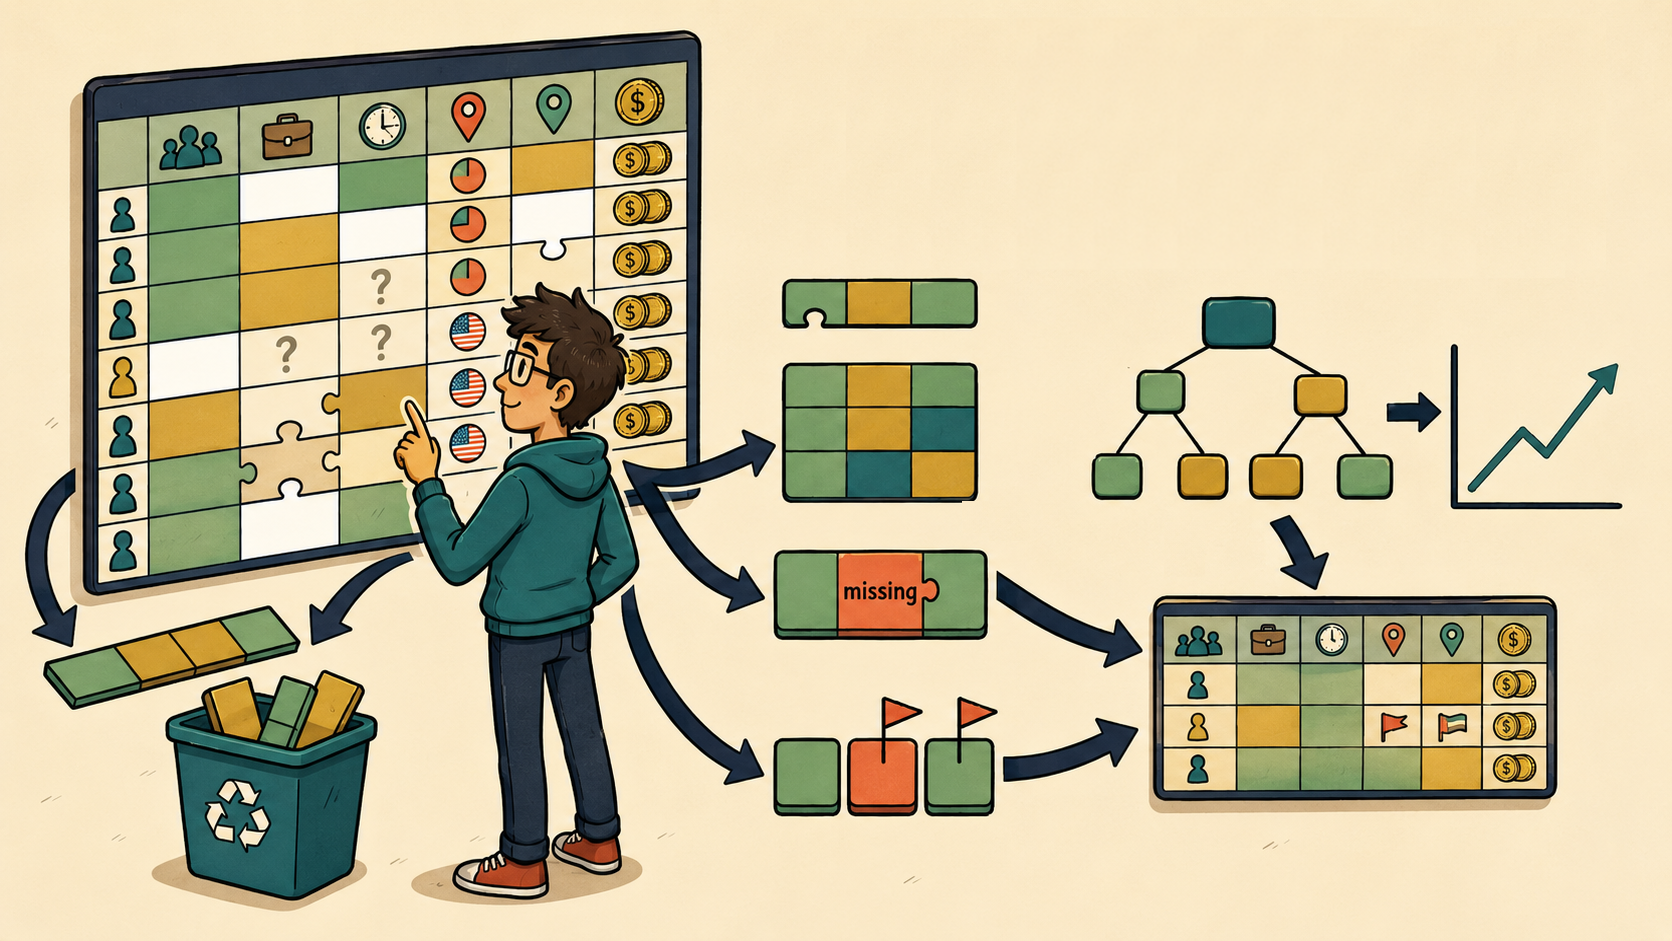
Missing values are not just a cleaning problem. The way you handle them can change the distribution of your data, introduce bias, and make an offline model evaluation look better than the model will perform in production.
The practical answer is to start by understanding why values are missing, establish a simple baseline, and compare alternatives using a validation strategy that keeps preprocessing inside the training workflow. In this guide, Part 1 covers the concepts and decisions. In Part 2, I compare deletion, simple imputation, KNN, and iterative imputation on the Titanic dataset.
Missing-data decision checklist
Before changing the data, ask:
- Which columns contain missing values, and how much is missing in each one?
- Is the same pattern present in the target or in important subgroups?
- Will the feature be available with the same missingness pattern when the model is used?
- Why might the value be missing: a random collection failure, a process decision, or because of the value itself?
- Can I compare this choice with a simple baseline on a clean validation set?
There is no percentage threshold that automatically tells you what to do. A feature with 1% missingness can still be problematic if those values are concentrated in one population, while a feature with much more missingness may remain useful if the pattern is understood and stable.
Why missing data matters
Missing data can reduce the sample size, distort relationships between variables, and make some groups disappear from an analysis. Deleting incomplete observations may therefore change the population represented by the training set. Imputation preserves rows, but it replaces unknown values with estimates and can understate uncertainty or create artificial patterns.
The right choice depends on the data-generating process, the model, the cost of errors, and what will be available at inference time.
Understand why values are missing: MCAR, MAR, and MNAR
Before choosing an imputation method, ask why the value is missing. A missing income value may be random, related to an observed feature such as employment type, or related to the income itself. Those cases require different assumptions.
| Mechanism | Meaning | Practical implication |
|---|---|---|
| MCAR | Missing Completely At Random: absence is unrelated to observed or unobserved data | Deletion is least problematic, though it still wastes data |
| MAR | Missing At Random: absence can be explained by observed variables | Imputation using relevant observed features can be reasonable |
| MNAR | Missing Not At Random: absence depends on the unobserved value itself | Simple imputation can be misleading; investigate the collection process and model missingness explicitly |
These mechanisms describe assumptions, not tests that can be proven from the observed data alone. In particular, MNAR usually requires domain knowledge about how the data was collected. See the University of Michigan notes on missing-data mechanisms for the statistical background.
Avoid data leakage when imputing missing values
Fit an imputer on the training data only. Then use that fitted imputer to transform validation, test, and production data.
If you calculate the median, nearest neighbours, or iterative imputation model using the full dataset before splitting, information from the test set leaks into training. Your offline evaluation will look better than the model will perform in production. A scikit-learn Pipeline makes the intended order explicit:
from sklearn.compose import ColumnTransformer
from sklearn.ensemble import HistGradientBoostingClassifier
from sklearn.impute import SimpleImputer
from sklearn.pipeline import Pipeline
from sklearn.preprocessing import OneHotEncoder

numeric_features = ["age", "income", "balance"]
categorical_features = ["region", "job_type"]

preprocessor = ColumnTransformer(
    transformers=[
        (
            "numeric",
            Pipeline(
                steps=[
                    ("imputer", SimpleImputer(strategy="median", add_indicator=True))
                ]
            ),
            numeric_features,
        ),
        (
            "categorical",
            Pipeline(
                steps=[
                    ("imputer", SimpleImputer(strategy="most_frequent")),
                    # HistGradientBoostingClassifier expects a dense matrix.
                    ("encoder", OneHotEncoder(handle_unknown="ignore", sparse_output=False)),
                ]
            ),
            categorical_features,
        ),
    ]
)

pipeline = Pipeline(
    steps=[
        ("preprocessor", preprocessor),
        ("model", HistGradientBoostingClassifier()),
    ]
)

pipeline.fit(X_train, y_train)
predictions = pipeline.predict(X_test)
The imputation statistics and encodings are learned from X_train inside fit. The fitted transformations are then applied consistently to X_test and to future production data.
Methods for handling missing values
The following comparison is a useful starting point. It is not a substitute for validation: missingness patterns, data types, and inference constraints matter more than the method’s popularity.
| Method | Use when | Main risk | Practical note |
|---|---|---|---|
| Drop rows | Missingness is genuinely rare and plausibly MCAR | Lost sample size and biased subsets | Apply cautiously; report how much data you discarded |
| Drop columns | A feature is unusable, weak, or unavailable at inference | Throwing away predictive signal | Consider coverage, usefulness, and production feasibility |
| Median, mode, or constant | You need a fast, robust baseline | Distorts distributions and reduces variance | Median is usually safer than mean for skewed numeric columns |
| Missing indicator | Missingness itself may be informative | Can encode collection artefacts | Pair it with imputation and validate on a clean holdout |
| KNN imputation | Similar observations are meaningful and data is not too large | Slow and distance-sensitive | Scale numeric features first; handle categoricals deliberately |
| Iterative imputation | Other variables are predictive of the missing feature | More assumptions and compute | Use inside a pipeline and compare with a simple baseline |
| Native missing-value models | The estimator supports NaN and missingness is present in production |
Support varies by implementation and model | Still validate feature availability and performance |
Drop rows or columns
Listwise deletion removes every row with at least one missing value. It is easy to understand, but it can discard a large or systematically different subset of the data. Dropping a column may be sensible when coverage is poor, the feature is weak, or it will not exist at prediction time. In either case, measure what you removed and check which groups are affected.
Pairwise deletion can be useful in some statistical analyses, but it is less natural for a single machine-learning feature matrix because different calculations may use different subsets of rows.
Simple imputation: median, mode, or a constant
Simple imputation replaces missing values with a summary value learned from the training data. Median imputation is a robust baseline for skewed numeric variables. Most-frequent imputation can work for categorical variables, while a dedicated value such as "Missing" preserves the fact that the value was absent.
Simple methods are fast and reproducible, but they can make the data look more concentrated than it really is. Always calculate the statistic inside the training pipeline, never across the full dataset.
Add a missingness indicator
A missingness indicator adds a feature recording whether the original value was missing. This can help when missingness is related to the target—for example, when a measurement is only collected for certain cases. It can also encode a temporary collection artefact, so validate it against a holdout that reflects production conditions. An indicator usually works best alongside imputation rather than as a replacement for it.
KNN imputation
KNNImputer uses nearby observations to fill a missing feature. “Nearby” depends on the distance metric, feature scaling, and how the variables are represented; it is not similarity in the abstract. KNN can be useful when similar rows really do have similar values, but it becomes expensive on large datasets and can be distorted by irrelevant or unscaled features.
from sklearn.impute import KNNImputer

imputer = KNNImputer(n_neighbors=5)
X_train_filled = imputer.fit_transform(X_train)
X_test_filled = imputer.transform(X_test)
In a real model, put the imputer and any scaler inside the same pipeline as the estimator.
Iterative and multiple imputation
IterativeImputer estimates each incomplete feature from the other features in repeated rounds. It can be useful when variables contain predictive relationships, but it adds modelling assumptions and computation. It is an iterative single-imputation tool by default; it is not automatically equivalent to multiple imputation.
Multiple imputation creates several plausible completed datasets and combines results so that uncertainty about the missing values is represented. MICE (Multiple Imputation by Chained Equations) is one family of multiple-imputation workflows. These methods are more involved than a single IterativeImputer call and should be repeated and combined deliberately when inferential uncertainty matters.
Models with native missing-value support
Some tree-based implementations can work with missing values directly. For example, XGBoost’s tree algorithms learn a default branch direction for missing values during training; they do not simply replace each missing value with a global statistic. This can be a useful baseline, but compare it against an explicit imputation pipeline.
Native support does not remove the need to understand whether missingness is informative, whether NaN will appear at inference time, or whether the chosen estimator actually supports it. Check the documentation for the exact implementation and estimator you plan to use.
How to choose a method
| If your situation is… | Start with… | Then validate… |
|---|---|---|
| A small fraction of numeric values is missing | Median imputation plus an indicator | Mean and no-indicator baselines |
| A categorical feature is missing | A dedicated Missing category or most-frequent imputation |
Whether missingness itself predicts the target |
| Features are related and missingness is substantial | Iterative imputation | The simple median/mode baseline |
| Similar rows are genuinely meaningful | KNN imputation | Scaled features and manageable data volume |
Your chosen tree model supports NaN |
Native missing-value handling | An explicit imputation pipeline |
| Values may be MNAR | Investigation and domain input | Sensitivity analysis; do not assume imputation fixes bias |
The comparison should use the same train/validation split, evaluation metric, and downstream model. Track not only predictive performance but also runtime, stability across splits, interpretability, and whether the transformed features match what production can provide.
A production-oriented example
For a more realistic workflow with mixed numeric and categorical features, see How to Handle Missing Data in Machine Learning: A Hands-On Example. It uses the UCI Adult Census Income dataset to compare deletion, mode imputation, missing-category handling, indicators, and model-based strategies.
Common mistakes
- Imputing before the train/test split.
- Choosing a method from a missing-value percentage alone.
- Treating missingness as harmless when it is concentrated in one subgroup.
- Using KNN without scaling numeric features or considering computational cost.
- Calling a single iterative imputation pass “multiple imputation.”
- Assuming native
NaNsupport means the missingness process no longer matters. - Evaluating only accuracy when missing values may affect calibration, recall, or subgroup performance.
Next: compare methods on the Titanic dataset
Want to see these approaches tested under the same conditions? Continue to Part 2, where I compare deletion, simple imputation, KNN, and iterative imputation on the Titanic dataset.